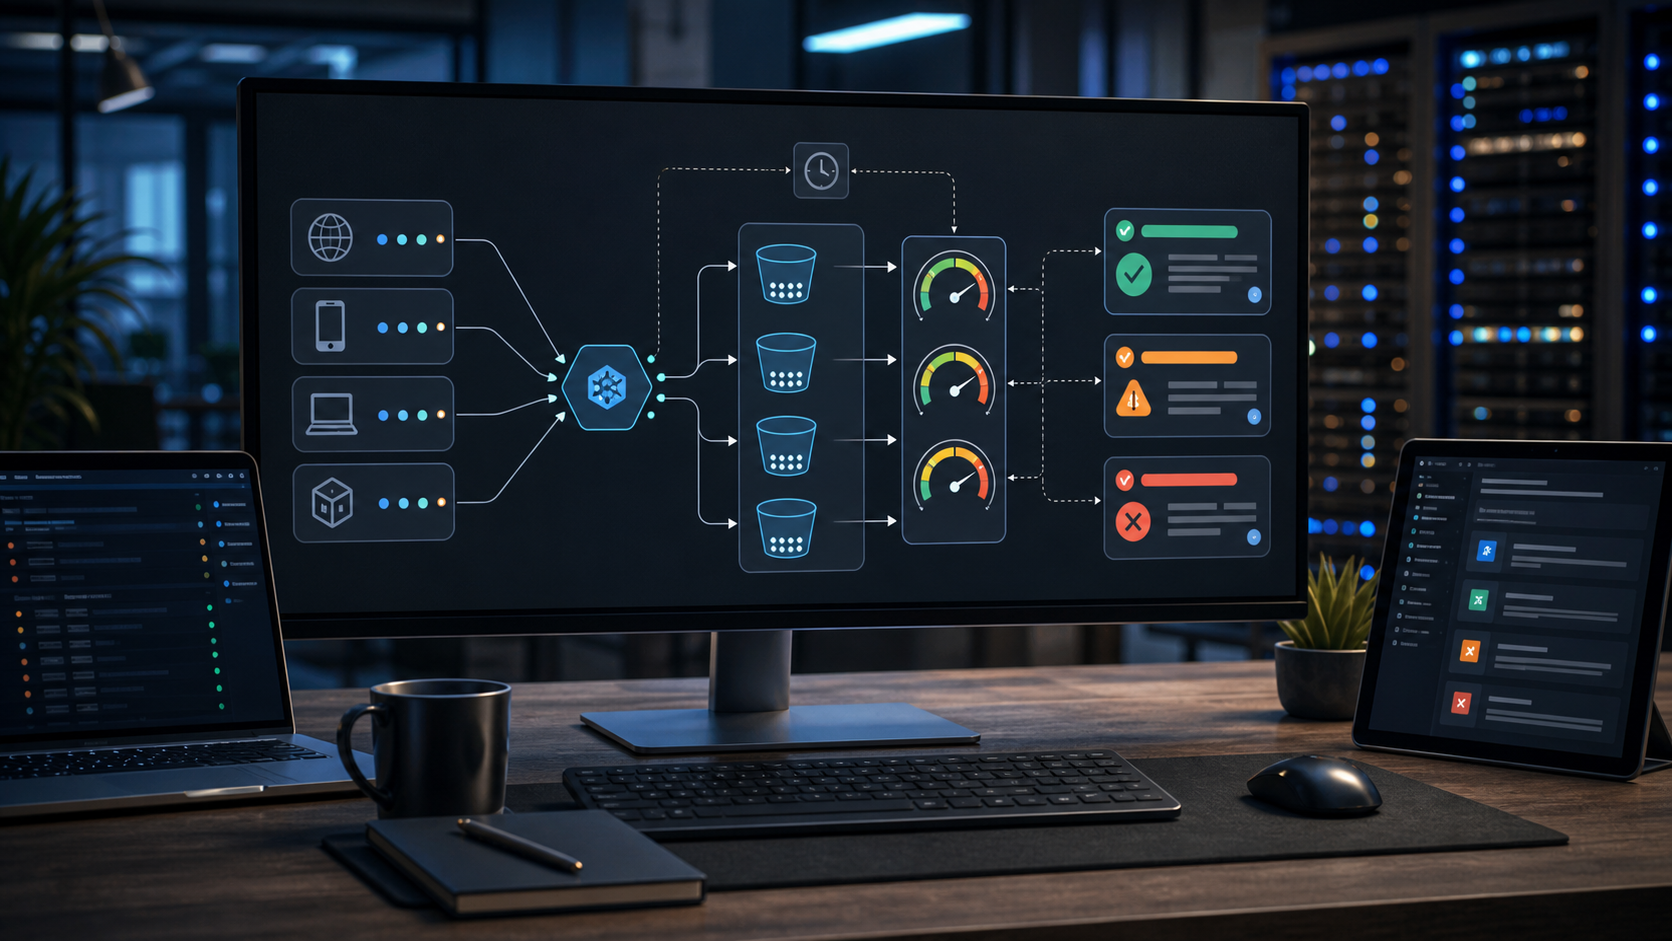
Error monitoring tools collect exceptions, crashes, and stack traces, but value comes from triage. Teams need rules for severity, ownership, duplicates, release association, and alerting thresholds.
Without a workflow, monitoring becomes a backlog of ignored red badges.
WHY IT MATTERS
Good triage reduces mean time to acknowledge and keeps production quality visible. It also helps developers connect defects to deployments and user journeys.
The workflow should keep noisy alerts out of critical channels while still preserving evidence for later debugging.
IMPLEMENTATION CHECKLIST
Build the triage workflow around ownership and user impact.
- Group errors by release, route, user impact, and affected account tier.
- Assign owners for major product areas and integrations.
- Set alert thresholds for new, escalating, or high-impact errors.
- Link errors to deployments, source maps, issue trackers, and runbooks.
- Close or mute issues with documented reasoning.
RISKS AND TRADEOFFS
The main risk is alert fatigue. If every exception is urgent, no exception is urgent.
The tradeoff is sensitivity. More alerts catch problems sooner but require stronger ownership and tuning.
BOTTOM LINE
Error monitoring needs a triage operating model. Route the right issues to the right owners with enough release context to act.